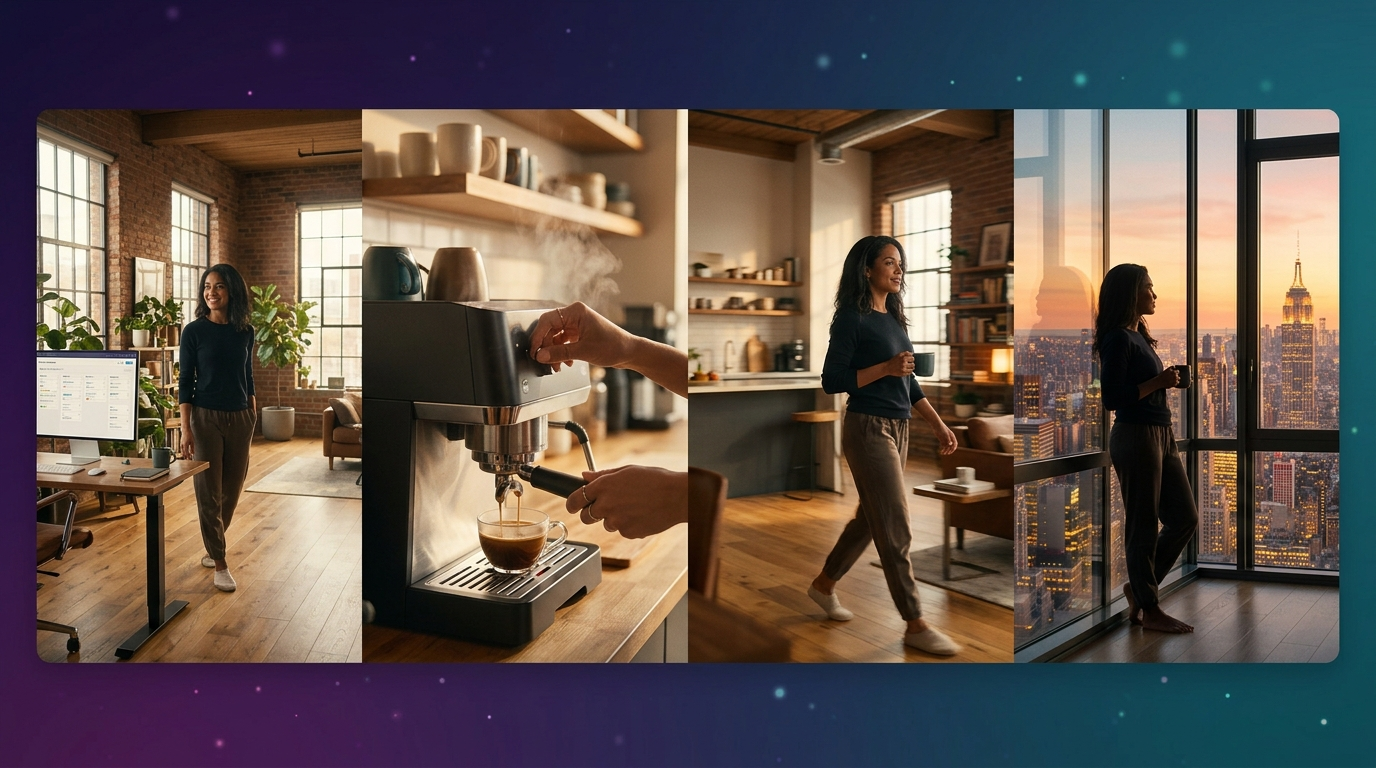
ByteDance announced Seedance 2.5 at its Volcano Engine FORCE conference in late June, introducing a video model that generates single clips up to 30 seconds long without any post-stitching, complete with scene changes and tempo shifts. This represents a generational leap from Seedance 2.0. Where most AI video tools cap at 5 to 15 seconds per clip, Seedance 2.5 generates full 30-second narratives in one pass.
This Seedance 2.5 guide explains what changed, why it matters for creators and agencies, and which production workflows benefit most from the upgrade. This is the most significant update to ByteDance's video generation family since the flagship Seedance 2.0 reached market leadership on independent benchmarks, and it is now available on Templix alongside the wider video model lineup.
For creators already producing content on Seedance 2.0, the upgrade path is straightforward: switch to Seedance 2.5 for any brief that would benefit from longer single-pass output, tighter reference control, or region-level editing capability. For creators new to the Seedance family, this guide covers everything you need to understand about the model, how it compares to alternatives on the Templix platform, and how to get the strongest output for your specific use case.
What Is Seedance 2.5
Seedance 2.5 is ByteDance's next-generation video model, announced as a deliberate generational jump from Seedance 2.0. ByteDance skipped versions 2.1 through 2.4 entirely and jumped straight from Seedance 2.0 to 2.5, framing it as a genuine generational leap rather than a point release. This Seedance 2.5 guide covers the three core upgrades: native 30-second single-clip generation, up to 50 multimodal reference inputs, and region-level editing that allows changing part of a frame without regenerating the entire video.
The model can process up to 50 additional inputs at once (reference images, audio, video, and more), which is genuinely useful for film scenes with multiple characters and complex brand requirements. This moves the model from creative experimentation territory into professional production territory. The change in reference capacity is not just a bigger number. It changes what kinds of productions the model can serve reliably.
Templix runs the full hosted version of Seedance 2.5, so users get access to the 4K-ready output and the complete reference system without the deployment overhead or regional restrictions that come with running the model outside a managed platform. Free credits on signup mean you can test Seedance 2.5 end to end at no cost before committing to a paid plan, which is genuinely useful when the value of a video model depends on how well it handles your specific briefs rather than how well it handles a demo reel.
Core Features in the Seedance 2.5 Guide
Seedance 2.5 addresses three specific production bottlenecks that Seedance 2.0 could not fully solve. Understanding each feature helps determine whether 2.5 is the right pick for your workflow, or whether one of the other models on Templix would fit better.
30-Second Native Video Generation
Seedance 2.5 generates single video clips up to 30 seconds long without any post-stitching, complete with scene changes and tempo shifts. This is the marquee feature and the core workflow change. Most competing models cap out at 5 to 15 seconds before quality degrades, requiring creators to stitch multiple clips together manually and hope the seams hold.
Thirty seconds is the length of a standard video ad spot, a short dance sequence, a complete product demonstration, or a full opening scene of a film preview. Single-pass generation removes the stitching step entirely, eliminates visible seams between clips, and maintains character and environmental consistency throughout the entire 30 seconds. For creators who were already producing 30-second content by stitching two or three shorter clips together, the switch to native 30-second generation removes the single most fragile step in the workflow.
Up to 50 Multimodal Reference Inputs
Up to 50 multimodal reference inputs, roughly a four times jump from the previous 12-reference limit, allow images, audio, and video to combine in one generation for keeping characters, products, and style consistent. This is the controllability upgrade. Instead of feeding the model one reference image, you can now provide a brand kit, voice samples, product mockups, lighting preferences, character sheets, and compositional templates all at once, and the model synthesises them into a coherent video.
The Seedance 2.5 guide emphasises this capability because it transforms AI video from an interesting experiment into a genuine production tool. For a brand producing dozens of marketing videos per month, this means defining the visual style once and ensuring every generated video adheres to it without re-engineering prompts from scratch for every asset.
Region-Level Editing Without Full Regeneration
Users can also edit generated Seedance 2.5 videos after generation while keeping the visual style and look intact. More specifically, region-level editing allows changing part of a frame (a character's position, a product angle, a background element) without requiring regeneration of the entire 30-second clip.
In traditional AI video workflows, if you disliked one element in a generated clip, you regenerated the entire thing, often losing the good parts while trying to fix the bad one. Region-level editing isolates the change, preserving the majority of the video while targeting the specific element that needs adjustment. This capability matters most for high-stakes production: if you have spent a full generation getting 29 seconds exactly right but one frame has a distracting background element, region editing fixes the specific frame without rolling the dice on regenerating 30 seconds hoping to preserve 29 of them.
Video Editing By Seedance 2.5
When you are editing an existing clip rather than generating from scratch, the source video has to be named explicitly as the sole editing master. From there, you specify the edit target, the edit scope, any target material, and exactly what has to stay untouched. A practical detail worth knowing before you start: the output automatically keeps the input video's aspect ratio and roughly preserves its duration. Neither can be set separately, and frame processing can shift timing by up to about 0.3 seconds, usually from how transition frames get handled. The event order and overall content stay substantially the same regardless.
The general editing pattern:
Edit @Video 1. Within the entire video or a specific time range, add, remove, replace, or adjust visual object, region, or audio category. @Video 1 is the sole editing master. It defines characters, scene, actions, composition, camera movement, occlusion relationships, audio, and event order. @Image 1 or @Audio 1 defines specified attributes of the target object or sound. Modify only object, region, time range, or audio category. Keep visual content, motion, audio, and timing relationships that must not change from @Video 1.
Applied to a real edit:
Edit @Video 1. Only from 4-7 seconds, change the cool blue light on the right wall to warm orange light. @Video 1 is the sole editing master. It defines the character, room layout, actions, composition, camera movement, audio, and event order. Change only the light colour on the right wall and the area it illuminates. Allow the character's skin tone to respond naturally to the environmental light. Keep the character's identity, clothing, expression, position, motion, room structure, camera movement, dialogue, and ambience from @Video 1.
Subject Replacement
Swapping one object for another inside an existing clip follows the same four-part structure, with a fifth piece added: timeline inheritance. This tells the model that the new object should adopt the exact timing, path, and speed changes the original object had.
A worked example, replacing a desk lamp mid-clip:
Edit @Video 1. Replace only the yellow folding desk lamp with the white folding desk lamp in @Image 1. @Video 1 is the sole editing master, defining the desk, books, hand movements, camera position, camera movement, occlusion relationships, and event order. @Image 1 defines only the white folding desk lamp's appearance, structure, and material. Do not use the image's background, composition, or other objects. Keep exactly one white folding desk lamp throughout the video. Replace only the original yellow folding desk lamp. Do not modify the books, desk, hands, or background. The white folding desk lamp inherits every appearance, lamp-arm rotation, hand occlusion, and exit of the original yellow folding desk lamp, including timing, path, and speed changes.
Background Replacement
The same logic applies to swapping an environment while keeping a subject completely untouched. The target reference should define only spatial layout, materials, depth of field, and lighting, explicitly excluding any people or foreground objects that happen to be in that reference image, since those would otherwise compete with your actual subject.
@Video 1 is the sole editing master. It defines the people, actions, composition, camera treatment, and event order. @Image 1 provides only the spatial layout, depth of field, ambient colour, and lighting direction of a daylit glass greenhouse. Do not use the people in the image. Replace only the light grey background outside the person's silhouette in @Video 1 with the daylit glass greenhouse from @Image 1. Keep the person's identity, facial features, hairstyle, clothing, expression, position, size, and arm-raising motion from @Video 1.
Audio Editing
Dialogue, language, voice, background music, and sound effects can each be edited independently. Name the speaker or sound category, state the intended change, and specify which other sounds have to stay exactly as they are.
Edit @Video 1. Remove only the original background music. Keep the character dialogue, lip sync, ambience, and action sound effects. Preserve the visuals, camera treatment, and editing rhythm from @Video 1.
For deeper prompt structure that produces the cleanest results across every generation, our JSON Prompting for AI Image Generation guide covers the structured approach that consistently outperforms free-text prompts. The same discipline applies directly to video prompting on Seedance 2.5.
Try Seedance 2.5 Video Editing Free
Video Extension of Seedance 2.5
Extension adds content beyond an existing clip's edge, and the direction matters. A forward extension's first frame has to continue directly from the source video's last frame. A backward extension's last frame has to connect to the source video's first frame. Beyond just matching that boundary frame, check that the characters, props, background, and events in the newly extended segment are actually correct. A clean boundary frame does not guarantee that everything after it holds up.
Forward Extension
Describe the continuous state of the last frame first, then describe what happens next.
@Video 1 is the source video to extend forward. Extend @Video 1 forward. The first frame of the extended segment directly continues from the last frame of @Video 1. Maintain continuity in subject pose and orientation, prop position, background and spatial relationships, camera position and composition, lighting, and motion direction. Then, describe the new action, event, camera treatment, or audio to add. Throughout the extension, maintain continuity in character identity and clothing, key props, background layout, and axis of action.
When you are adding new reference materials alongside the extension, define every material's role first, then make it clear the source video still controls the extension's opening frame. New materials can supplement characters, props, or audio, but they do not override that boundary control.
Backward Extension
Backward extension works in the opposite direction: describe what happens before the source video begins, then explicitly define the source video's first frame as the end state the extended segment has to reach. Writing only "then connect to the source video" without that explicit end-state description risks introducing characters or effects too early, or causing the image to shift again right after it reaches the target state.
@Video 1 is the source video to extend backward. Extend @Video 1 backward. Before the source video begins, describe the preceding action, event, camera treatment, or audio. The last frame of the extended segment naturally connects to the first frame of @Video 1: subject pose and orientation, prop position, and background and spatial relationships. Match the camera position and composition, lighting, and motion direction of @Video 1's first frame. Throughout the extension, maintain continuity in character identity and clothing, key props, background layout, and axis of action.
When additional reference materials are involved in a backward extension, state explicitly which materials belong in the preceding segment and which should only appear once the source video actually begins. This is what keeps a later character or prop from showing up too early in the backstory you are generating. Regardless of direction, remember that boundary frames need to connect naturally at a visual level, not match pixel-for-pixel, so review both sides of the boundary and the full extended segment together rather than judging the cut point in isolation.
Advanced Techniques: Keyframes, Storyboards, and Blockout References
These three techniques give you more control than a single continuous-action prompt allows: locking exact start and end frames, sequencing multiple stages in order, or building a scene around a rough layout reference.
First and Last Frames, With Additional References
In multimodal reference mode, you can state directly that one image is the first frame and another is the last, without switching to a separate mode for it. The system locks the output's aspect ratio to the first image specifically, so keep the first and last images at matching aspect ratios. A mismatch can stretch the last frame. Duration still gets set separately on the generation page or through the API. Additional images beyond the two anchors can still define characters, props, and other scene materials, but they should never be allowed to override the compositions the first and last frame images establish.
A worked example, a perfumer finishing a bottle:
@Image 1 is the first frame, defining the opening composition, character positions, poses, tabletop prop states, perfume-workshop scene, and camera direction. @Image 2 is the last frame, defining the ending composition and equivalent details. @Image 3 defines the perfumer's face, hairstyle, and dark green apron, without changing either anchor composition. Starting from the first-frame pose, the perfumer picks up a dropper and the glass perfume bottle, drips amber fragrance oil into the bottle, swirls it gently, closes the stopper, places the finished bottle in the centre of the table, and naturally reaches the last frame.
One structural note worth flagging directly: describe each anchor image in its own sentence. Do not combine them into something like "@Images 1 and 2 are the first and last frames," since that collapses two distinct roles into one ambiguous instruction.
Multi-Keyframe Sequence Control
When several images define different stages of a process rather than just a start and end point, open with "use @Image 1 through @Image N as keyframes in this order," then describe the key state each individual image represents. Independent keyframe images hold up better than several frames combined into one grid, and it is worth being clear that keyframes control stage order and key states. They do not guarantee every single frame in between matches exactly.
Use @Image 1 through @Image 4 as keyframes in this order. @Image 1 is the first frame, showing an orange paper airplane resting on the left side of a classroom desk, pointed right, in a locked-off medium shot. @Image 2 defines the second keyframe: a hand lifts the same airplane without changing its direction. @Image 3 defines the third keyframe: the airplane passes the window while the curtain moves slightly. @Image 4 is the last frame: the airplane rests on the bookcase shelf, still pointed right. The video passes through these states in order, using continuous action to transition naturally between stages.
Storyboard Grids
A storyboard grid communicates overall story structure, shot order, and rough composition, not a panel-by-panel exact reproduction. Keep it to 15 panels or fewer, favour clean line art or simple diagrams over anything text-heavy, and state the reading order explicitly (left to right, top to bottom, or whatever order actually applies) before describing each panel's subject action, shot size or camera movement, and the audio and visual style for the finished result.
Blockout References: Coarse vs Fine
Blockout references split into two categories, and knowing which one you are actually supplying changes how you should prompt around it.
Type | Best For | Material Requirements | Prompt Focus |
Coarse Blockout | Previewing simple geometry, action blocking, character paths, camera movement, and shot sequencing. | Use clear spatial relationships between objects with a complete action sequence. Character, prop, and scene reference images can be supplied separately. | Map every blockout subject and clearly specify which temporal and spatial information the model should inherit during generation. |
Fine Blockout | Detailed scene reconstruction with new characters, materials, colours, environments, or artistic styles. | Provide a complete, clean 3D model. Avoid including path guides, coordinate axes, camera frustums, or editor overlays in the reference. | Preserve the original structure, camera treatment, and action while explicitly describing what should be re-rendered or replaced. |
A coarse blockout is mainly carrying timing and spatial information: action, paths, blocking, camera movement, lighting, sound. So your prompt's job is naming what it should inherit from that structure. A fine blockout already has a complete shape, so your prompt's job shifts to defining materials, colour, character identity, and visual style to render onto that existing form, rather than describing the structure itself all over again.
Seedance 2.5 vs Seedance 2.0
The Seedance 2.5 guide separates incremental improvements from true architectural changes. Seedance 2.0 already ranked first on independent benchmarks. Seedance 2.5 addresses its main limitations: clip length, reference control, and frame-level editing precision. For a deep dive on the specific differences, our Seedance 2.5 vs Seedance 2.0 comparison guide walks through the full spec breakdown.
Dimension | Seedance 2.0 | Seedance 2.5 |
Native Clip Length | About 15 seconds max | 30 seconds, single-pass |
Reference Inputs | About 12 combined | Up to 50 multimodal |
Resolution | 720p, 1080p | 4K-ready |
Scene Changes | Limited | Built into the 30-second generation |
Tempo Shifts | Not native | Built into the 30-second generation |
Editing Capability | Full re-roll | Region-level redraw |
Best For | Short-form, social | Long-form narrative, commercial |
The practical difference: on Seedance 2.0, a 30-second commercial requires stitching 2 to 4 smaller clips together, with visible seams and character continuity issues that need manual cleanup afterwards. On Seedance 2.5, a single 30-second generation produces a seamless full commercial with scene changes and consistent characters throughout. Test both on Templix to measure the difference directly for your specific brief.
Use Cases for Seedance 2.5
The Seedance 2.5 guide identifies five core production workflows where the 30-second barrier and region editing create genuine operational value.
Commercial Advertising and Ad Production
Standard 30-second video commercials are now a single generation on Seedance 2.5. Brands can test 20 creative variants, select the strongest 3, and move those to the final edit without the stitching and continuity challenges that plagued previous workflows. For media agencies and creative teams, this compresses production timelines and reduces per-asset cost meaningfully.
The Templix Ad Studio, running on Seedance 2.5 among other models, enables full-motion ad production at agency scale without a traditional shoot. Use this Seedance 2.5 guide to plan your creative testing workflow.
Film and Television Production Previews
Directors and cinematographers use Seedance 2.5 to preview scenes before commissioning actual shoots. A 30-second preview of a complex multi-character scene, complete with specific camera movements and lighting, costs far less than a full film shoot and provides the feedback needed to refine direction well before any actual production budget commits.
For production studios, this means earlier design iteration and lower revision costs. This Seedance 2.5 guide emphasises this use case because it represents a genuine shift in production methodology, not just faster rendering of what was already possible.
Short-Form Drama and Series Production
Short-form drama platforms including TikTok, Instagram, and YouTube Shorts require weekly or daily episodic content. A 30-second scene with consistent characters and narrative flow, generated in one pass, enables creators to produce drama series at a pace and cost that would be impossible with traditional production. Serialised storytelling formats fit particularly well within the 30-second window because the runway matches how modern social platforms actually surface short-form content to viewers.
For creators building audiences through serialised narrative content, Seedance 2.5 removes the bottleneck entirely. This Seedance 2.5 guide frames this as a fundamental shift in creator economics: storytelling at social media velocity without traditional video production overhead.
Product Demonstrations and E-Commerce Content
Product videos over 15 seconds were essentially impossible on previous tools without stitching multiple clips together. On Seedance 2.5, a complete product showcase (unboxing, feature callout, lifestyle use, call-to-action) fits in one generation. For e-commerce and product marketing, this is significant for conversion-focused video content that needs to hold viewer attention for the full runway before the call-to-action lands.
Complex Multi-Character Scenes With Consistency
With 50 reference inputs available, Seedance 2.5 handles multi-character scenes where every character needs visual consistency, correct positioning, and synchronised motion. Dialogue scenes, group performances, action sequences, and ensemble compositions are all now possible in a single pass without the character drift that plagued previous approaches.
This Seedance 2.5 guide notes that this is where professional production requirements finally align with AI video capabilities. Static image tools excel at composed portraits. Seedance 2.5 excels at dynamic multi-element sequences that hold together for a full 30 seconds.
Seedance 2.5 vs Other AI Video Generators
The Seedance 2.5 guide positions 2.5 against other leading models. On the independent Artificial Analysis Video Arena, the shipping Seedance 2.0 leads text-to-video and image-to-video, ahead of Google Veo 3.1 and Kling 3.0 at a fraction of their cost. No 2.5 benchmark exists yet, but the 30-second claim is unique in the current market.
Seedance 2.5 vs MiniMax H3
MiniMax H3 is the other major new video model on the platform. H3 leads on native 2K output, synchronised stereo audio in the same pass, and multi-shot scenes within a single 15-second clip. Seedance 2.5 leads on longer single-pass generation (30 seconds versus H3's 15 seconds) and larger reference input capacity. For dialogue-driven or audio-first content, H3 is often the stronger pick. For longer atmospheric shots and full-length commercial spots, Seedance 2.5 has the advantage. Testing both on your specific brief is the fastest way to decide.
Seedance 2.5 vs Kling 3.0
Kling 3.0 Pro supports strong motion control and expressive character animation. Seedance 2.5 supports 50 references and 30-second generation. Kling 3.0 remains competitive for motion-heavy content and shorter clips. Seedance 2.5 is stronger for narrative complexity and brand consistency over longer sequences. Both are professional-tier tools. Choose based on your clip length and reference requirements for the specific brief.
Conclusion
Seedance 2.5 generates single video clips up to 30 seconds long without any post-stitching, complete with scene changes and tempo shifts. This represents a genuine capability leap in AI video production, moving from "create short clips and stitch them" to "create full sequences in one pass."
For commercial production, film previsualization, drama series, and professional video work requiring 50-reference consistency, Seedance 2.5 removes the bottlenecks that made AI video impractical for professional timelines. Free credits on signup mean you can test it end to end at no cost before committing to a paid plan.
Start Using Seedance 2.5 Free on Templix
Frequently Asked Questions
What is the maximum clip length on Seedance 2.5?
Seedance 2.5 generates single video clips up to 30 seconds long in one pass, without any post-stitching required. This is the marquee upgrade over Seedance 2.0, which topped out at around 15 seconds per clip.
How many reference inputs can Seedance 2.5 accept?
Up to 50 multimodal reference inputs: images, video, audio, and text combined in one generation. This is roughly a four times jump from the previous 12-reference limit, and it is what enables the model to serve complex brand and character consistency requirements at professional production scale.
Does Seedance 2.5 support text-to-video and image-to-video?
Yes. This Seedance 2.5 guide confirms text-to-video and reference-to-video based on announcement details. The 50-reference capability implies multimodal support, including images and audio, in every generation mode.
Is Seedance 2.5 free to use on Templix?
Yes. Templix offers free credits on signup so you can test Seedance 2.5 and every other model on the platform at no cost. Paid plans unlock higher credit volumes and priority processing for teams producing at scale.
How does Seedance 2.5 compare to Seedance 2.0?
Seedance 2.5 is a generational upgrade rather than a point release. Key differences: 30 seconds native clip length (vs about 15 seconds), up to 50 multimodal references (vs about 12), 4K-ready output (vs 720p and 1080p), built-in scene changes and tempo shifts, and region-level editing rather than full re-roll for any change. For the deep dive, see our dedicated Seedance 2.5 vs 2.0 guide.
Can I edit Seedance 2.5 videos after generation?
Yes. Region-level editing allows changing part of a frame while keeping the visual style and the rest of the video intact. Subject replacement, background replacement, and independent audio editing all work through structured prompt patterns covered in this guide.
How does Seedance 2.5 compare to Google Veo 3.1?
Both are top-tier video models with different strengths. Veo 3.1 emphasises visual realism and atmospheric detail. Veo 3.1 tops out at 15-second generation. Seedance 2.5 doubles that to 30 seconds. Veo 3.1 may retain an edge in pure cinematic photorealism. Seedance 2.5 wins on length and reference control. For commercial production and narrative work, Seedance 2.5's 30-second native capability is a decisive advantage.
How does Seedance 2.5 compare to MiniMax H3?
MiniMax H3 leads on native 2K output, synchronised stereo audio, and multi-shot scenes within a single 15-second clip. Seedance 2.5 leads on longer single-pass generation and larger reference input capacity. For dialogue-driven content, H3 is often stronger. For longer atmospheric shots, Seedance 2.5 has the advantage.
Can I use Seedance 2.5 output commercially?
Yes. Videos generated on Templix using Seedance 2.5 are available for commercial use across social content, product pages, paid ads, brand campaigns, editorial work, and any other commercial application. This applies to output from every model available on the Templix platform.
What is the biggest reason to switch from Seedance 2.0 to Seedance 2.5?
Native 30-second single-pass generation removes the biggest fragility point in AI video production: the stitching step. Every seam between clips introduces a chance of character drift, environmental inconsistency, or visible cut edges that need cleanup. Removing that step entirely turns 30-second commercial production from a delicate multi-step process into a single-generation workflow, which is what makes the upgrade meaningful for professional production teams.
Mahnoor Asad
Mahnoor Asad blends design sensibility with AI video expertise at Templix, crafting content on visual creativity, motion generation, and high-converting ad concepts.